> ## Documentation Index
> Fetch the complete documentation index at: https://docs.rekody.com/llms.txt
> Use this file to discover all available pages before exploring further.
# Engines
> Rekody Streaming, local Whisper, and the optional cloud engines.
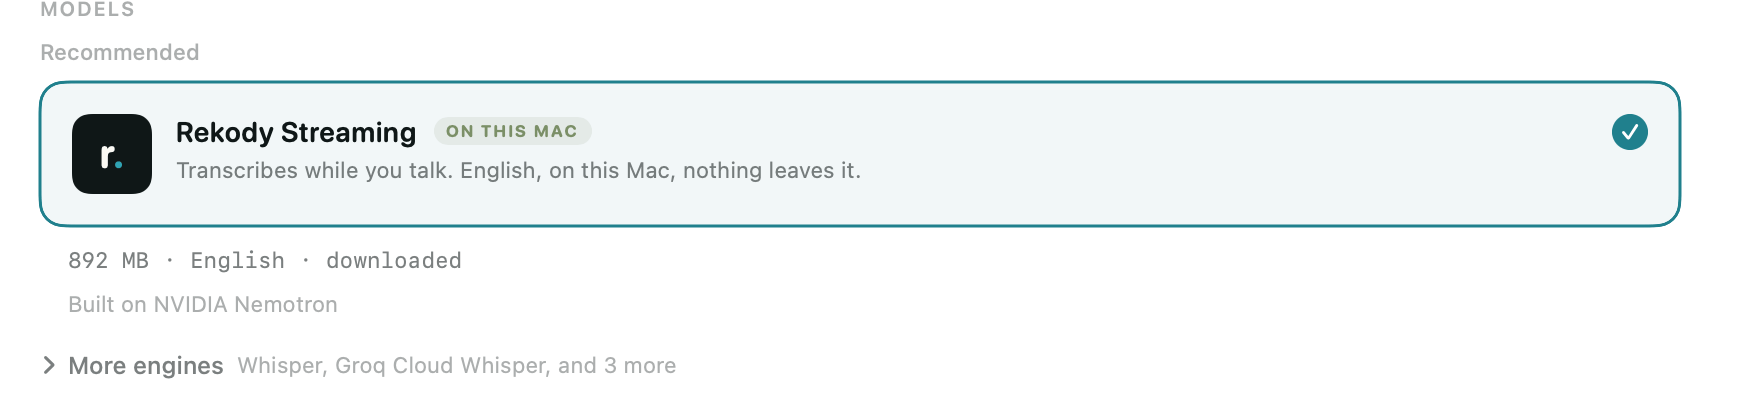
Rekody's speech-to-text is pluggable. Pick an engine in `rekody setup` or set `stt_engine` in [config.toml](/developers/configuration). The Mac app exposes the same engines in Settings, where the streaming model is the default.
Every surface reads one table, the provider catalog in `rekody-core/src/stt_catalog.rs`. `rekody engines` prints it, and `rekody engines --json` prints the machine-readable form the Mac app's Settings page is generated from, so the list can never differ between the CLI, the wizard, and the app.
 | Engine | Where it runs | Release to text | Notes |
| - | - | - | - |
| `nemotron` (Rekody Streaming) | On device | \~50ms | Transcribes while you talk. English. Apple Silicon. The setup default. |
| `local` (Whisper) | On device | 1 to 3s | whisper.cpp with Core ML acceleration on Apple Silicon. |
| `deepgram` | Cloud | \~200ms | Nova-3 with smart formatting. Needs a Deepgram API key. |
| `groq` | Cloud | \~300ms | Whisper Large v3 on Groq. Needs a Groq API key. |
| `gemini` | Cloud | 2 to 4s | Google `gemini-3.5-transcribe`, batch. Needs a Google AI Studio API key. |
| `cohere` | Local server | varies | Talks to a local STT server on a configurable port. |
| `custom` | Wherever you point it | varies | Any endpoint speaking OpenAI's `/v1/audio/transcriptions`. Opt-in only. |
## Rekody Streaming
The flagship engine is the **Rekody Streaming model** ([`Rekody/rekody-streaming-en-0.6b-160ms-int8`](https://huggingface.co/Rekody/rekody-streaming-en-0.6b-160ms-int8)), an int8 ONNX conversion of NVIDIA's Nemotron speech streaming 0.6B checkpoint, packaged by Rekody for on-device dictation.
What makes it different from every other engine here: it is **cache-aware streaming ASR**. Audio is transcribed in 160ms chunks as it arrives, with encoder state carried across chunks, so your words appear while you are still talking. Batch engines wait for the full recording before emitting anything; the streaming engine has almost nothing left to do when you release the key.
The chunk length is a property of the model file, not of Rekody: the cache-aware right context is baked into the export, and the runtime reads it from the artifact's ONNX metadata. An older 560ms artifact still loads and is still driven correctly at its own profile, so an upgrade that has not yet re-run `rekody setup` degrades to the old latency rather than breaking.
* Fully on device: no audio leaves the machine.
* English only, and the download is about 890 MB across three files.
* Runs on the CPU via ONNX Runtime; Apple Silicon is the supported target.
### Benchmarks
Word error rate (WER, %), lower is better. Measured with the Open ASR Leaderboard methodology (`hf-audio/open-asr-leaderboard` @ `b6bdcd0b`, `EnglishTextNormalizer`), on identical audio and with the identical normalizer for both models.
These numbers were measured on the **560ms** export. The leaderboard has not been re-run at 160ms, so they are reported as what they are rather than restated for the current artifact. NVIDIA's own per-chunk table for this checkpoint puts the 560ms-to-160ms difference at +0.60 pp on the eight-set average, of which AMI, the far-field multi-party meeting set, contributes +2.83 pp on its own; across the other seven sets the difference is +0.28 pp.
| Dataset | rekody-streaming-en-0.6b-int8 (560ms) | openai/whisper-large-v3-turbo |
| - | - | - |
| AMI | 12.36 | 13.86 |
| Earnings22 | 12.27 | 10.81 |
| Gigaspeech | 8.64 | 8.34 |
| LibriSpeech test-clean | 2.09 | 1.60 |
| LibriSpeech test-other | 4.92 | 3.75 |
| SPGISpeech | 2.99 | 2.78 |
| Voxpopuli | 2.74 | 5.31 |
| **Average** | **6.57** | **6.64** |
Note the operating points: the Rekody model streams, producing text as audio arrives, while `whisper-large-v3-turbo` is a batch model that sees each full recording before emitting anything. Matching a strong batch model's average WER under a streaming constraint is the point of this model.
The cost of int8 quantization was measured as statistically zero: on LibriSpeech test-clean (n = 2620), int8 differs from the fp32 export it came from by +0.072 pp WER with a paired bootstrap 95% CI of \[-0.004, +0.150], which includes zero. Full details are on the [model card](https://huggingface.co/Rekody/rekody-streaming-en-0.6b-160ms-int8).
## Local Whisper
`stt_engine = "local"` runs whisper.cpp on device. Pick a size with `whisper_model`:
| `whisper_model` | Download | Character |
| - | - | - |
| `turbo` | 574 MB | Near-large accuracy. Fast **only on Apple Silicon**, where the encoder runs on the Neural Engine. Recommended there. |
| `tiny` | 75 MB | Fastest, basic accuracy. |
| `small` | 488 MB | Balanced. Recommended on Intel Macs. |
| `medium` | 1.5 GB | Better accuracy. |
| `large` | 3.1 GB | Best accuracy (large-v3 weights). |
Setup preselects the size that suits the machine it is running on: `turbo` on
Apple Silicon, `small` where there is no Neural Engine. `turbo` is
`large-v3-turbo`, whose decoder is cut from 32 layers to 4 but whose encoder
is the full 32-layer large-v3 encoder, and whisper.cpp pays that encode once
per dictation against a zero-padded 30 second window. On the Neural Engine
that is cheap; on a CPU it is a large-model encode after every sentence.
Measure before overriding the default: `rekody bench --model tiny --model
small --model turbo` runs each size on a bundled clip and prints mean latency
plus real-time factor. The size to keep is the largest one that stays
comfortably faster than real time on your machine.
Setup installs the multilingual model files; set `stt_language` to a specific code when you know the language in advance, or leave it unset for auto-detect.
On Apple Silicon, setup also fetches the matching **Core ML encoder** so the encoder pass runs on the Neural Engine. The first transcription afterwards takes 30 to 60 seconds while macOS compiles the model; every run after that is fast. Elsewhere there is no Core ML encoder and no GPU path (Rekody builds whisper.cpp with Metal off on every target), so the encoder runs on the CPU.
## Cloud engines
Cloud engines are strictly opt-in and use your own API keys ([privacy details](/app/privacy)).
* **Deepgram** (`stt_engine = "deepgram"`): Nova-3. Because its `smart_format` already returns clean, punctuated text, Rekody auto-disables LLM post-processing for this engine unless you force `llm_enabled = true`.
* **Groq** (`stt_engine = "groq"`): Whisper Large v3 behind Groq's API.
* **Gemini** (`stt_engine = "gemini"`): Google's `gemini-3.5-transcribe`, sent in one request with the audio inline. Measured 2 to 4 seconds for a 5.5 second clip, so it is a batch engine and not a streaming one.
The model transcribes in one of two modes, and Rekody chooses which rather than offering it as a setting. `verbatim` returns every word, including filler and abandoned starts. `smart` removes them: "Let's meet Tuesday, no, Wednesday, um, to review the numbers" comes back as "Let's meet Wednesday to review the numbers", with nothing to say an edit happened.
Rekody uses **verbatim whenever `save_training_data` is on** (the default), and smart only when it is off. The reason is that Rekody files each dictation's audio next to its transcript as a fine-tuning dataset, and a smart transcript stored there is a label that does not match its audio. Run `rekody doctor` to see which mode is active.
Personal dictionary terms are forwarded as `custom_vocabulary`, capped at the first 50 in file order.
* **Cohere** (`stt_engine = "cohere"`): a local STT server reached on `cohere_stt_port` (default 8099).
## Other (any OpenAI-compatible endpoint)
`stt_engine = "custom"` points Rekody at any service that answers OpenAI's `/v1/audio/transcriptions`: OpenAI itself, Together, Fireworks, or a vLLM or LM Studio server you run. Groq is the same shape and ships as a preset of the same engine.
```toml theme={null}
stt_engine = "custom"
custom_stt_base_url = "https://api.openai.com/v1"
custom_stt_model = "whisper-1"
custom_stt_api_key = "" # optional: a local server usually needs none
```
Because you supply the address your voice is sent to, this engine is fenced:
* **https is required**, with one exception: plain `http` is accepted on localhost and other loopback addresses, so self-hosting works.
* **The destination host is shown before it is used**, in Settings, in `rekody engines`, in `rekody doctor`, and in the run-loop header.
* **It is never a default and never a fallback.** Nothing selects it for you, and if the URL or model is missing Rekody refuses to start rather than guessing.
* **A wrong endpoint fails in plain language.** If the server answers with something other than a transcription, the message says so and quotes what came back, instead of surfacing a parse error.
## LLM post-processing
After transcription, an optional LLM pass cleans filler words, fixes grammar, and adapts formatting to the focused app. Only the transcript text is sent to an LLM provider, never audio.
Providers are configured as an ordered `[[providers]]` chain: each is tried in turn and the first success wins. If every provider fails, the raw transcript is injected, so dictation never breaks. On macOS 26 with Apple Intelligence, the `apple` provider cleans up on device with no download and no API key.
See the [config.toml reference](/developers/configuration#llm-providers) for the full provider list and fields.
This documentation is built and hosted on [Mintlify](https://mintlify.com), a developer documentation platform.